Friday, 17 December 2021

Universe 3: Fonts

The Universe project uses Google Noto fonts as much as possible. As the Noto project page says:

The name is also short for "no tofu", as the project aims to eliminate 'tofu': blank rectangles shown when no font is available for your text.

According to the Universe Statistic page UCD 14.0.0, there are 144,762 "used" codepoints. This breaks down as follows when you include "unused" codepoints such as "private", "surrogate" and "noncharacter":

Kind Criteria Codepoints
format gc is "Cf", "Zl" or "Zp" 165
control gc is "Cc" 65
private gc is "Co" 137,468
surrogate gc is "Cs" 2,048
noncharacter gc is "Cn" 66
modifier gc is "Mc", "Me" or "Mn" 2,408
emoji EPres is "Y" 1,185
graphic otherwise 140,939
Total 284,344

Note that this "Kind" classification is slightly more fine-grained than Unicode's "basic type" but less so than "general category". Also note that the codepoints classified as "private", "surrogate" and "noncharacter" are fixed and will not change in subsequent Unicode versions.

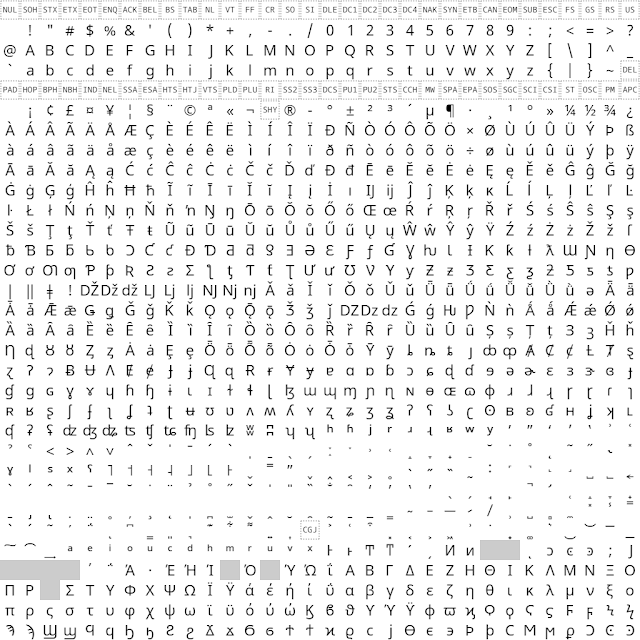
This still leaves a great many codepoints that need to be rendered. The relationship between Unicode codepoints and character glyphs within a font is non-trivial, to say the least; but it can be useful, in a character browser, to render an "archetype" glyph of each codepoint for illustrative purposes.

In Universe, each "used" codepoint has a 32-by-32 pixel bitmap glyph. The aim is to use Google Noto fonts wherever possible to construct these bitmaps, because:

  1. Noto fonts are "free and open source".
  2. Their codepoint coverage is relatively good.
  3. They try to adhere to a consistent look and feel.

Consequently, I named the set of bitmap glyphs "Notoverse". One can think of Notoverse as an alternative to GNU's Unifont initiative, except:

  • The glyphs are 32-by-32, not 16-by-16.
  • The glyphs are 24-bit RGB, not 1-bit monochrome.
  • There is full Unicode 14.0.0 coverage.

The construction of the Notoverse glyphs was tedious and exhausting. I now know why so many similar projects run out of steam. The final breakdown of sources for each of the 144,762 glyphs is as follows:

It turns out that Noto contributes to about 54% of the glyphs; more if we include the glyphs manually constructed from Noto elements.

U+0061: LATIN SMALL LETTER A

Here is the list of the Google Noto fonts I used (in priority order):

  • Noto Sans
  • Noto Sans Armenian
  • Noto Sans Hebrew
  • Noto Sans Arabic
  • Noto Sans Syriac
  • Noto Sans Thaana
  • Noto Sans NKo/Noto Sans N Ko
  • Noto Sans Samaritan
  • Noto Sans Mandaic
  • Noto Sans Malayalam
  • Noto Sans Devanagari
  • Noto Sans Bengali
  • Noto Sans Gurmukhi
  • Noto Sans Gujarati
  • Noto Sans Oriya
  • Noto Sans Tamil
  • Noto Sans Tamil Supplement
  • Noto Sans Telugu
  • Noto Sans Kannada
  • Noto Sans Malayalam
  • Noto Sans Sinhala
  • Noto Sans Thai
  • Noto Sans Myanmar
  • Noto Sans Georgian
  • Noto Sans Cherokee
  • Noto Sans Canadian Aboriginal
  • Noto Sans Ogham
  • Noto Sans Runic
  • Noto Sans Tagalog
  • Noto Sans Hanunoo
  • Noto Sans Buhid
  • Noto Sans Tagbanwa
  • Noto Sans Khmer
  • Noto Sans Mongolian
  • Noto Sans Limbu
  • Noto Sans Tai Le
  • Noto Sans New Tai Lue
  • Noto Sans Buginese
  • Noto Sans Tai Tham
  • Noto Sans Balinese
  • Noto Sans Sundanese
  • Noto Sans Batak
  • Noto Sans Lepcha
  • Noto Sans Ol Chiki
  • Noto Sans Glagolitic
  • Noto Sans Coptic
  • Noto Sans Tifinagh
  • Noto Sans Yi
  • Noto Sans Lisu
  • Noto Sans Vai
  • Noto Sans Bamum
  • Noto Sans Syloti Nagri
  • Noto Sans PhagsPa
  • Noto Sans Saurashtra
  • Noto Sans Kayah Li
  • Noto Sans Rejang
  • Noto Sans Javanese
  • Noto Sans Cham
  • Noto Sans Tai Viet
  • Noto Sans Ethiopic
  • Noto Sans Linear A
  • Noto Sans Linear B
  • Noto Sans Phoenician
  • Noto Sans Lycian
  • Noto Sans Carian
  • Noto Sans Old Italic
  • Noto Sans Gothic
  • Noto Sans Old Permic
  • Noto Sans Ugaritic
  • Noto Sans Old Persian
  • Noto Sans Deseret
  • Noto Sans Shavian
  • Noto Sans Osmanya
  • Noto Sans Osage
  • Noto Sans Elbasan
  • Noto Sans Caucasian Albanian
  • Noto Sans Cypriot
  • Noto Sans Imperial Aramaic
  • Noto Sans Palmyrene
  • Noto Sans Nabataean
  • Noto Sans Hatran
  • Noto Sans Lydian
  • Noto Sans Meroitic
  • Noto Sans Kharoshthi
  • Noto Sans Old South Arabian
  • Noto Sans Old North Arabian
  • Noto Sans Manichaean
  • Noto Sans Avestan
  • Noto Sans Inscriptional Parthian
  • Noto Sans Inscriptional Pahlavi
  • Noto Sans Psalter Pahlavi
  • Noto Sans Old Turkic
  • Noto Sans Old Hungarian
  • Noto Sans Hanifi Rohingya
  • Noto Sans Old Sogdian
  • Noto Sans Sogdian
  • Noto Sans Elymaic
  • Noto Sans Brahmi
  • Noto Sans Kaithi
  • Noto Sans Sora Sompeng
  • Noto Sans Chakma
  • Noto Sans Mahajani
  • Noto Sans Sharada
  • Noto Sans Khojki
  • Noto Sans Multani
  • Noto Sans Khudawadi
  • Noto Sans Grantha
  • Noto Sans Newa
  • Noto Sans Tirhuta
  • Noto Sans Siddham
  • Noto Sans Modi
  • Noto Sans Takri
  • Noto Sans Warang Citi
  • Noto Sans Zanabazar Square
  • Noto Sans Soyombo
  • Noto Sans Pau Cin Hau
  • Noto Sans Bhaiksuki
  • Noto Sans Marchen
  • Noto Sans Masaram Gondi
  • Noto Sans Gunjala Gondi
  • Noto Sans Cuneiform
  • Noto Sans Egyptian Hieroglyphs
  • Noto Sans Anatolian Hieroglyphs
  • Noto Sans Mro
  • Noto Sans Bassa Vah
  • Noto Sans Pahawh Hmong
  • Noto Sans Medefaidrin
  • Noto Sans Miao
  • Noto Sans Nushu
  • Noto Sans Duployan
  • Noto Sans SignWriting
  • Noto Sans Wancho
  • Noto Sans Mende Kikakui
  • Noto Sans Meetei Mayek/Noto Sans MeeteiMayek
  • Noto Sans Adlam Unjoined
  • Noto Sans Indic Siyaq Numbers
  • Noto Serif Tibetan
  • Noto Serif Vithkuqi
  • Noto Serif Yezidi
  • Noto Serif Ahom
  • Noto Serif Dogra
  • Noto Serif Tangut
  • Noto Serif Hmong Nyiakeng/Noto Serif Nyiakeng Puachue Hmong
  • Noto Sans Symbols
  • Noto Sans Symbols2/Noto Sans Symbols 2
  • Noto Sans Math
  • Noto Sans Display
  • Noto Looped Lao
  • Noto Sans Lao
  • Noto Sans CJK SC/Noto Sans SC
  • Noto Music
Where there are two font names with a slash between them, the first is the local font name and the second the web font name. Alas, the naming is somewhat lax. See the HTML source and CSS for more details.

I hope I haven't trodden on anyone's toes by using their fonts in this way. The individual glyphs are down-sampled to 32-by-32 pixels and used for illustrative purposes only. I trust you'll agree that's "fair use".

So, it looks like we're still a long way from getting a pan-Unicode font, or even a set of fonts that achieve the same goal.

For completeness, here's a list of attempts at providing good Unicode coverage:

Thursday, 16 December 2021

Universe 2: Loading Resources

When the Universe web page first loads into a browser, about 100MB of data are pulled over the network in over 250 HTTP requests. This includes 77 web fonts (6MB), 161 glyph image sheets (77MB) and the Unicode Character Database, UCD, as a tab-separated value file (28MB).

It can take three or four minutes the first time around with a slow network connection, but all these resources are usually cached by the browser, so subsequent page loads perform very little actual data transfer. However, decoding the UCD is another matter.

Even the subset of the UCD data we're actually interested in takes up a quarter of a gigabyte when expressed as JSON. So caching the raw JSON file is problematic. I elected to transfer the data as sequential key-value deltas in TSV format. This reduces the size down to under 30MB and only 6.5MB when compressed "on the wire". It is also relatively quick to reconstitute the full UCD object hierarchy in JavaScript: it takes about seven seconds on my machine.

Here are the lines describing codepoint U+0040 ("@"):

na<tab>COMMERCIAL AT
lb<tab>AL
STerm<tab>N
Term<tab>N
SB<tab>XX
0040
<tab>= at sign

The first five lines (in "<key><tab><value>" form) list only the differences in UCD properties (keyed by short property aliases) compared to the preceding codepoint (i.e. U+003F "?").

The next line (in "<hex>" form) creates a new codepoint record for "U+0040".

The final line (in "<tab><extra>" form) adds an extra line of narrative to the preceding record. In this case, it refers to a NamesList.txt alias.

The ucd.14.0.0.tsv file is constructed using a NodeJS script from the following sources:

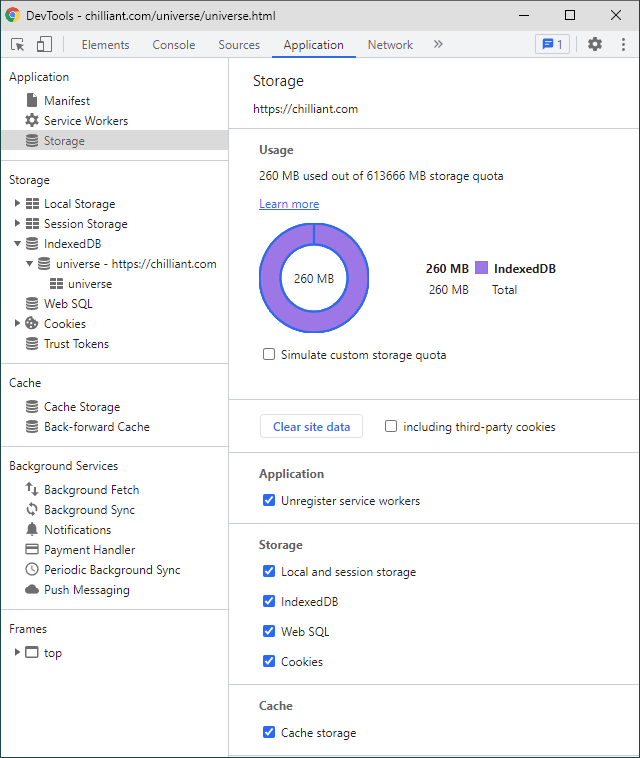
It is read and reconstituted by the "LoadDatabaseFileAsync()" function of universe.js. Notice that the final action of that function is to store the data in an IndexedDB database. This allows the JavaScript to test for the existence of that data in subsequent page reloads, obviating the need to fetch and decode each time. This saves several seconds each time. See "IndexedDatabaseGet()" and "IndexedDatabasePut()" in universe.js.

The downside of using this client-side caching is that it takes up 260MB of disk space:


We rely on the browser (Chrome, in this case) to manage the IndexedDB storage correctly, but even if the cache is purged, we fall back over to parsing the TSV again.

Wednesday, 15 December 2021

Universe 1: Introduction

Version 14.0.0 of Unicode was released back in September. There are an plethora of online resources for browsing the Unicode Character Database (UCD):

But they usually have something lacking: the ability to render the codepoints and/or keeping up-to-date with the ever-evolving Unicode standard.

Of course, you can just download the official Unicode code charts as a single PDF and manually cross-reference them with the UCD. But the PDF is over 100MB and the UCD is distributed as a collection of human-unfriendly text files.


Universe is my attempt at producing a client-side HTML/CSS/JavaScript Unicode browser. It's obviously a work in progress, but the main areas of interest (that I plan to cover in subsequent blog posts) are:

  1. A user interface to navigate around Unicode codepoints, blocks, planes, etc.
  2. Loading the UCD into the client (this is my biggest concern at present as it takes about ten seconds to load and parse the database).
  3. A flexible search mechanism.
  4. Font support.
  5. A representative rendering of all the codepoints.

Saturday, 16 October 2021

Voronoi

I've just been baking. But what do you think of when you see the results?

  1. Biscuits
  2. Cookies
  3. Voronoi

Depending on your answer:

  1. You're probably British
  2. You're probably American
  3. You're definitely a geek

Thursday, 7 October 2021

Machin Postage Stamps 3

I've done some investigation into Machin stamp designs that take into account colour vision deficiency (CVD). In particular, I looked at CVD-safe colour schemes and visual representation of numerals for the denominations. See those three web pages for more details.

The numeral scheme I finally came up with (after a lot of experimentation) is as follows:

The symbols have the following properties:

  1. The number of small dots is the value of the digit.
  2. Each has a high-contrast, CVD-safe colour (from the 'Chilliant Pale/Deep 19' palette).
  3. The outlines are distinct.
  4. They all fit within a circle the size of the grey ring zero.

For dark backgrounds, simply switch the pale/deep pairings:

The names I've ascribed to each of the symbols are:

  • 0: grey ring
  • 1: slate circle
  • 2: brown oval
  • 3: purple triangle
  • 4: cyan cross
  • 5: green bowtie
  • 6: pink star
  • 7: blue heptagon
  • 8: orange square
  • 9: mint lozenge

Monday, 4 October 2021

Daltonism

Machin stamps are colour-coded according to their denomination. The coding scheme is somewhat ad hoc. But what if we wanted to be more systematic?

There are surprising few existing systems for encoding numbers as colours. One is the old system used for electronic components:

The digits zero to nine are represented by ten colours. My favourite mnemonic is:

Black Bananas Really Offend Your Girlfriend, But Violets Get Welcomed

In the past, colour-blind people were allegedly discouraged from becoming electricians because of the possibility of confusing earth (green), live (red) and neutral (black) in the pre-1977 UK domestic mains cabling colour scheme.

In an ideal world, the mapping of colours to numeric values would be fairly immune to any colour vision deficiency (CVD) experienced by the viewer. This led me to an investigation into colour-blindness: what used to be called "Daltonism" in the UK.

There are plenty of resources on the web explaining the various forms of colour blindness, but I wanted to be able to objectively assess how "good" a palette of colours was for:

  1. People with no colour deficiency (I'll call them "trichromats"),
  2. People with protanopia, deuteranopia or tritanopia ("dichromats"), and
  3. People with monochrome vision ("monochromats").

One metric of how well a palette of colours "fills" a colour space is to measure the minimum "distance" between any two entries. I chose the CIELAB colour space and the CIEDE2000 metric because they were close-at-hand as part of my previous Goldenrod project.

I defined lambda as the minimum distance (ΔE2000) between colours in the palette as seen by trichromats; also known as minD(normal). The greater this number, the less likely that two entries within the palette will be confused by trichromats.

I then used a corrected version of Color.Vision.Simulate from HCIRN to simulate the four colour deficiencies and produce four "confused" palettes from the original:

  1. protanope
  2. deuteranope
  3. tritanope
  4. achromatope

Each of the confused palettes will have a minimum distance between colours within them; call these minimum distances minD(protanope), etc.

I defined beta as the minimum of minD(protanope), minD(deuteranope) and minD(tritanope). The greater this number, the less likely that two entries within the original palette will be confused by dichromats. I appreciate that there are far fewer sufferers of tritanopia in the general population than of the other two forms of dichromatism, but I haven't scaled the three distance metrics accordingly; I'm running under the premise of "none left behind".

I defined alpha to be minD(achromatope). The greater this number, the less likely that two entries within the original palette will be confused by monochromats.

Finally, I defined omega to be the minimum distance between two adjacent CIELChab hues from the original palette, measured in degrees. This number measures hue separation perceived by trichromats.

In summary:

  • Lambda, λ, is "min ΔE2000" for the original, trichromatic palette. It measures how different the colours in the palette seem to a viewer with no colour vision deficiency. Larger values indicate greater variation.
  • Beta, β, is the least "min ΔE2000" for the dichromatic remappings of the palette. It measures how different the colours in the palette seem to a viewer with one of those colour vision deficiencies. Larger values indicate greater variation.
  • Alpha, α, is "min ΔE2000" for the achromatic remapping of the palette. It measures how different the colours in the palette seem to a viewer with achromatopsia, when rendered in greyscale or in some low-light conditions. Larger values indicate greater variation.
  • Omega, ω, is "min Δhab" for the original, trichromatic palette. It measures the perceived hue separation (measured in degrees) experienced by a viewer with no colour vision deficiency. Larger values indicate greater separation.

Unfortunately, as the number of entries in a palette increases, we expect the λ, β, α and ω scores to decrease, so we cannot easily compare palettes with differing numbers of entries. Perhaps the scores could be scaled depending on the palette size, but I haven't tried to work out the factor; I suspect it's not linear.

In general, for our purposes, a "good" palette is one with high λ, β and/or α scores. Maximising λ is appropriate for about 92% of the population; β for about 8%; and α for less than 0.01%.

The accompanying web page computes the scores for existing and novel palettes.

If we take "Chilliant Pale/Deep 19" from that page and re-order the palette into hue order, we get a colour-blind-friendly scheme with which to encode the digits zero to nine:

This could be the basis for a new colour-coding of stamp denominations...

Friday, 17 September 2021

Unicode Numeral Systems

As part of my investigations into Machin stamps, I started looking at numeral systems for labelling stamp denominations and also clock faces.

Unicode 13.0.0 contains a few General Categories used to classify code points according to numeric value ("Nd", "Nl" & "No") plus Derived Numeric Types ("Decimal", "Digit" & "Numeric"). Trawling through these and the Wikipedia pages on numeral systems, I came up with well over one hundred systems that can be used to represent numbers in Unicode using single glyphs:

Unicode Numerals web page

As it turns out, this experiment became more of an exercise in font management. I initially used Unifont for rendering, but this is quite ugly. The Code2000 fonts are no longer maintained. I ended up using Googles Noto fonts. However, there doesn't seem to be a definitive list of which glyphs exist in which font, so I had to create a tool to interrogate all the Noto web fonts I could find. Even an online list of those web fonts seems lacking, so here's one:

  • Noto Kufi Arabic
  • Noto Naskh Arabic
  • Noto Naskh Arabic UI
  • Noto Nastaliq Urdu
  • Noto Sans
  • Noto Sans JP
  • Noto Sans KR
  • Noto Sans SC
  • Noto Sans TC
  • Noto Sans Adlam
  • Noto Sans Adlam Unjoined
  • Noto Sans Anatolian Hieroglyphs
  • Noto Sans Arabic
  • Noto Sans Arabic UI
  • Noto Sans Armenian
  • Noto Sans Avestan
  • Noto Sans Balinese
  • Noto Sans Bamum
  • Noto Sans Batak
  • Noto Sans Bengali
  • Noto Sans Bengali UI
  • Noto Sans Bhaiksuki
  • Noto Sans Brahmi
  • Noto Sans Buginese
  • Noto Sans Buhid
  • Noto Sans Canadian Aboriginal
  • Noto Sans Carian
  • Noto Sans Chakma
  • Noto Sans Cham
  • Noto Sans Cherokee
  • Noto Sans Coptic
  • Noto Sans Cuneiform
  • Noto Sans Cypriot
  • Noto Sans Deseret
  • Noto Sans Devanagari
  • Noto Sans Devanagari UI
  • Noto Sans Display
  • Noto Sans Egyptian Hieroglyphs
  • Noto Sans Ethiopic
  • Noto Sans Georgian
  • Noto Sans Glagolitic
  • Noto Sans Gothic
  • Noto Sans Gujarati
  • Noto Sans Gujarati UI
  • Noto Sans Gurmukhi
  • Noto Sans Gurmukhi UI
  • Noto Sans Gunjala Gondi
  • Noto Sans Hanifi Rohingya
  • Noto Sans Hanunoo
  • Noto Sans Hebrew
  • Noto Sans Imperial Aramaic
  • Noto Sans Indic Siyaq Numbers
  • Noto Sans Inscriptional Pahlavi
  • Noto Sans Inscriptional Parthian
  • Noto Sans Javanese
  • Noto Sans Kaithi
  • Noto Sans Kannada
  • Noto Sans Kannada UI
  • Noto Sans Kayah Li
  • Noto Sans Kharoshthi
  • Noto Sans Khmer
  • Noto Sans Khmer UI
  • Noto Sans Khudawadi
  • Noto Sans Lao
  • Noto Sans Lao UI
  • Noto Sans Lepcha
  • Noto Sans Limbu
  • Noto Sans Linear B
  • Noto Sans Lisu
  • Noto Sans Lycian
  • Noto Sans Lydian
  • Noto Sans Malayalam
  • Noto Sans Malayalam UI
  • Noto Sans Mandaic
  • Noto Sans Masaram Gondi
  • Noto Sans Mayan Numerals
  • Noto Sans Medefaidrin
  • Noto Sans MeeteiMayek
  • Noto Sans Mende Kikakui
  • Noto Sans Meroitic
  • Noto Sans Modi
  • Noto Sans Mongolian
  • Noto Sans Mono
  • Noto Sans Mro
  • Noto Sans Myanmar
  • Noto Sans Myanmar UI
  • Noto Sans New Tai Lue
  • Noto Sans Newa
  • Noto Sans Ogham
  • Noto Sans Ol Chiki
  • Noto Sans Old Italic
  • Noto Sans Old Persian
  • Noto Sans Old South Arabian
  • Noto Sans Old Turkic
  • Noto Sans Oriya
  • Noto Sans Oriya UI
  • Noto Sans Osage
  • Noto Sans Osmanya
  • Noto Sans Pahawh Hmong
  • Noto Sans Phags Pa
  • Noto Sans Phoenician
  • Noto Sans Rejang
  • Noto Sans Runic
  • Noto Sans Samaritan
  • Noto Sans Saurashtra
  • Noto Sans Sharada
  • Noto Sans Shavian
  • Noto Sans Sinhala
  • Noto Sans Sinhala UI
  • Noto Sans Sundanese
  • Noto Sans Syloti Nagri
  • Noto Sans Symbols
  • Noto Sans Symbols 2
  • Noto Sans Syriac
  • Noto Sans Tagalog
  • Noto Sans Tagbanwa
  • Noto Sans Tai Le
  • Noto Sans Tai Tham
  • Noto Sans Tai Viet
  • Noto Sans Takri
  • Noto Sans Tamil
  • Noto Sans Tamil UI
  • Noto Sans Telugu
  • Noto Sans Telugu UI
  • Noto Sans Thaana
  • Noto Sans Thai
  • Noto Sans Thai UI
  • Noto Sans Tifinagh
  • Noto Sans Tirhuta
  • Noto Sans Ugaritic
  • Noto Sans Vai
  • Noto Sans Wancho
  • Noto Sans Warang Citi
  • Noto Sans Yi
  • Noto Serif
  • Noto Serif JP
  • Noto Serif KR
  • Noto Serif SC
  • Noto Serif TC
  • Noto Serif Ahom
  • Noto Serif Armenian
  • Noto Serif Bengali
  • Noto Serif Devanagari
  • Noto Serif Display
  • Noto Serif Ethiopic
  • Noto Serif Georgian
  • Noto Serif Gujarati
  • Noto Serif Hebrew
  • Noto Serif Kannada
  • Noto Serif Khmer
  • Noto Serif Lao
  • Noto Serif Malayalam
  • Noto Serif Myanmar
  • Noto Serif Nyiakeng Puachue Hmong
  • Noto Serif Sinhala
  • Noto Serif Tamil
  • Noto Serif Telugu
  • Noto Serif Thai
  • Noto Serif Tibetan

The Font Check tool allows you to type in a hexadecimal Unicode code point and see the fonts that can render it. It uses the trick of measuring the glyph using an offscreen canvas with a fallback font of Adobe Blank. If the glyph is zero pixels wide, it means it was rendered using the fallback (or is naturally zero-width, so isn't of interest to us anyway).

Using the tool, I worked out the minimal set of Noto fonts needed to render the numerals table. However, there were a few issues:

  1. Some fonts only come in serif variants, not sans serif (and vice versa).

  2. I couldn't find any Noto web fonts that could render the following (though the asterisked scripts were rendered correctly using a fallback font by my browser):

    • Dives Akuru
    • Khmer Divination*
    • Myanmar Tai Laing*
    • Nko*
    • Ottoman Siyaq
    • Sinhala*
    • Sora Sompeng*
    • Tag

  3. Arabic Persian and Arabic Urdu use exactly the same codepoints but use different languages in the HTML mark-up to select different sets of glyphs.

Further notes:

  • I couldn't find any information on how Ogham represented numbers, so I made something up based on tally marks.
  • The Tibetan script has a parallel set of numerals for half values; they're used in stamps, which is a nice coincidence.
  • The Runic Golden Numbers are used in Younger Futhark calendars.
  • Other scripts do have numerals or counting systems, but I excluded many because they are "low radix" (e.g. native Korean)